MCP server

An MCP server for my working system

5 notes · 9 min

How I built an MCP server for my working system: illustration 1

Contents

  1. Why I separated memory from execution2 min
  2. How the LLM got access to my Obsidian2 min
  3. What happens when an LLM searches my memory2 min
  4. How an LLM reaches the local Obsidian on my Mac1 min
  5. Where MCP ends and what comes next2 min

Why I separated memory from execution

At some point the amount of information I work with became too large.

Projects, technical decisions, tasks, diagrams, notes, interim conclusions.

While a project is active, it feels as if all its logic is in your head. But switch to other work and come back a few weeks later, and part of the context has to be rebuilt from scratch.

I needed a system that stores not just notes, but the state of a project.

One of the first approaches was Apple Freeform. The idea of a canvas suited me right away: laying information out in space, seeing connections, assembling a project as more than linear text.

But it soon became clear that one canvas wasn’t enough.

I needed ordinary files, Markdown, a clear folder structure, Canvas, an API, and the ability to build my own rules on top of all of it.

That’s how Obsidian became the main memory.

But another problem appeared almost immediately.

Obsidian is a good place to keep project architecture, technical decisions, documentation, reasons for changes, plans and history.

But day-to-day task execution is better kept separately.

For that I kept Todoist.

At first the natural idea seemed to be to link the two systems as tightly as possible: changes in Obsidian show up in Todoist, changes in Todoist come back.

In practice that symmetry quickly creates new problems.

Which one wins if the data diverges?

What counts as the current state of the project?

Should a task change be written back into the documentation?

In the end I arrived at a simpler architecture.

Obsidian stores memory.

Todoist manages execution.

The detailed state of a project lives in files. For example, the current plan is in implementation_plan.md, and the history of important decisions is kept in decisions_log.md.

Todoist doesn’t try to become a second copy of that memory. It shows what needs to be done now.

Out of this, one of the main rules of my whole system gradually emerged.

One fact = one owner.

If it’s a project decision, it belongs to project memory.

If it’s an action to be carried out, it belongs to the execution layer.

The link between them remains, but they no longer try to be mirrors of each other.

And here the next question appeared.

If the real project memory is in Obsidian, how do you give a language model access to exactly that, instead of moving documents into the chat by hand every time?

The first working answer to that question was my Obsidian MCP server.

In the next post I’ll go through how the LLM got access to my Obsidian through it.

Back to contents

How the LLM got access to my Obsidian

Once I had separated project memory from execution, the next problem appeared.

Obsidian already held all the information I needed about my projects: architecture, implementation plans, technical passports, decision history, Canvas and related documents.

But the language model couldn’t see that memory.

Until I pasted the right file into the chat myself, it effectively didn’t exist for the model.

I could have searched for implementation_plan.md by hand every time, copied the right notes, added related documents and explained where the project currently stood.

But then the very idea of project memory loses much of its point.

I needed access to the real Obsidian, not yet another copy of its contents inside a chat.

That’s how MCP entered the system.

In my case the MCP server works as an interface between the language model and Obsidian.

It gives the model a set of concrete tools: view a project’s structure, find a note, search the vault, read a file, or edit an ordinary note on direct request.

The whole of Obsidian is not loaded into the model.

The LLM only gets tools through which it can reach the information it needs on its own.

For example, if I ask what’s happening in a particular project, there’s no need to hand the model the whole project in advance.

It can find it, open implementation_plan.md, turn to decisions_log.md or other related documents if needed, and only then form an answer.

Technically there’s one more layer between the model and the files.

The MCP server talks to Obsidian through the Local REST API, and Obsidian itself works with the real vault on my Mac.

So the chain looks like this:

LLM

MCP server

Obsidian Local REST API

Obsidian vault

What matters to me here is the principle.

Project memory stays in files and remains the source of truth.

The LLM doesn’t keep a separate copy of the project’s state and doesn’t need me to assemble context for it by hand every time.

It gets the ability to turn to memory when that memory is actually needed.

It was after this that Obsidian finally stopped being just a place where notes sit.

It became working memory that language models and other tools can connect to through a formal interface.

Today this MCP setup remains my main way of giving an LLM access to Obsidian.

But the tool call itself hides quite a lot of interesting mechanics.

In the next post I’ll go through what actually happens when an LLM looks for something in my memory: how it chooses a tool, how the request passes through MCP, and why the model doesn’t get the whole vault as one big context.

Back to contents

What happens when an LLM searches my memory

In the last post I explained that MCP gives the language model access to Obsidian.

But access alone doesn’t mean the model receives the entire vault.

When I ask a question about a project, the system works differently.

First the LLM decides which tool it needs.

For example, if it has to understand the current state of a project, it may start by searching the relevant area of Obsidian.

After that MCP returns not the whole project but a list of matching files and fragments.

And only then does the model open the documents actually needed for the answer.

In simplified form the chain looks like this:

question

search within the project

files found

reading the needed documents

assembling context

answer

For me this is a fundamental part of the architecture.

If the vault holds hundreds of projects and thousands of files, handing them all to the model is pointless.

Most of the information has nothing to do with the current question and only adds noise.

So the model moves through memory step by step.

For example, the real search-first protocol inside my MCP setup looks roughly like this:

searchInPath: Projects/Systems/PRJ-002 Network

query: internet OR VPN OR DNS OR MacStudio OR “Mac Studio” OR “MacBook Air” OR route OR routing OR split

First the search area is set.

Then, with one query, the system tries to get a wide enough set of candidates.

After that only the most relevant files are read.

This approach didn’t appear just to save context.

At some point I ran into the Obsidian MCP rate limit.

If the model starts guessing file names and making many sequential requests, the server may return 429 and temporarily stop further access.

So a separate principle appeared in the project:

search first, read later.

Don’t guess files one by one.

Don’t read the whole project in advance.

Don’t keep sending requests after a 429.

Find the area, run one wide search, and choose sources from the result.

Technically the MCP client itself also works through a sequence of separate operations.

First an MCP session is created.

Then the client gets the list of available tools.

After that the model can call a specific tool and pass it parameters.

In simplified form:

initialize

mcp-session-id

tools/list

tools/call

So MCP is not a channel through which all of Obsidian constantly flows into the LLM.

It’s more like a set of doors into project memory.

The model decides which door to open, gets a small piece of information and moves on if needed.

That’s exactly why this approach turned out to be more convenient for me than loading documents into the chat by hand.

I can ask about a project I haven’t touched for weeks, and the model will find its current state, read the right sources and rebuild the context from real files.

But so far we’ve only talked about the logic of access.

There’s one more question: how does a remote LLM even call an MCP server that physically runs on my Mac?

In the next post I’ll go through the whole path of a request, from the external model to the local Obsidian.

Back to contents

How an LLM reaches the local Obsidian on my Mac

Obsidian, the vault and the MCP server all run locally on my Mac.

For an external LLM to reach that memory, a separate transport layer is needed.

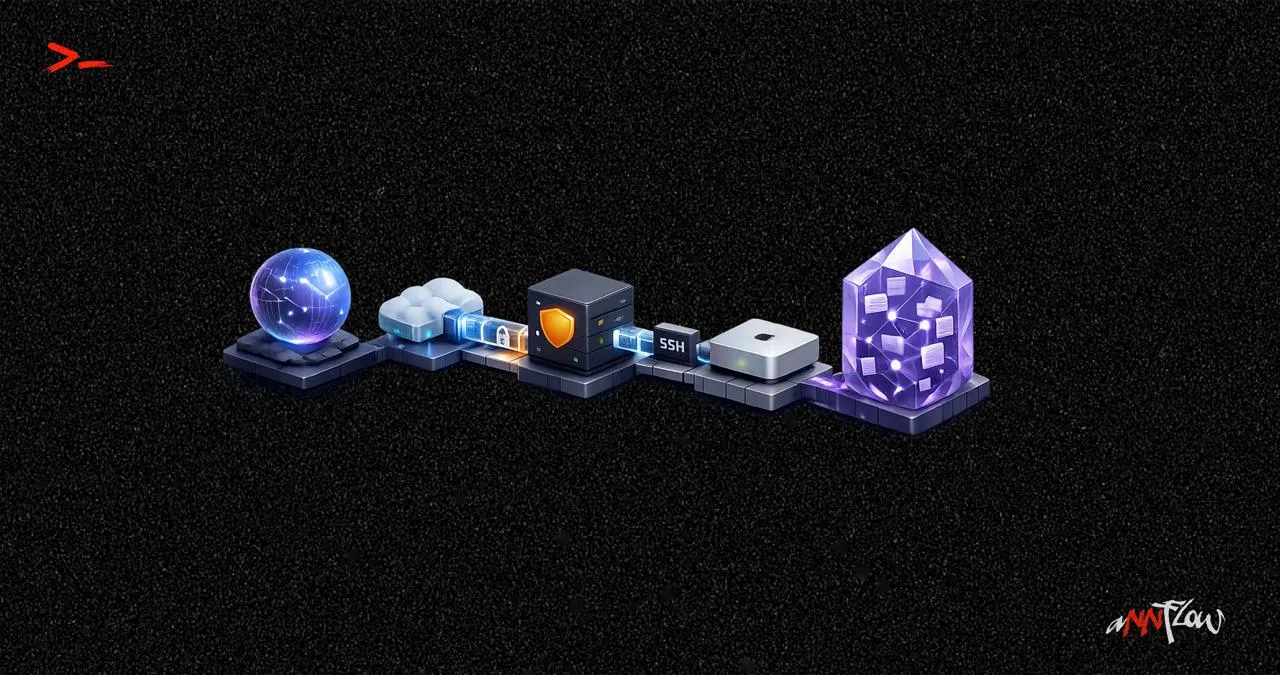
The current setup looks like this:

LLM / MCP client

Cloudflare

VPS

reverse SSH

MCP server on the Mac

Obsidian Local REST API

Obsidian vault

The public entry point is a separate MCP endpoint.

Cloudflare accepts the request and passes it to the VPS, where cloudflared directs the traffic to:

127.0.0.1:3011

But the MCP server itself isn’t on the VPS.

Port 3011 is created by a reverse SSH tunnel that my Mac brings up on its own.

The key fragment:

-R 127.0.0.1:3011:127.0.0.1:3010

So everything that arrives at 3011 inside the VPS is sent over SSH to local MCP port 3010 on my Mac.

From there the request stays inside the local system:

MCP server

Obsidian Local REST API

vault

In this architecture the VPS remains only a transport layer.

It doesn’t store the vault, doesn’t index notes and doesn’t become a second copy of project memory.

Even port 3011 is only reachable inside the VPS.

Obsidian itself stays local.

For stable operation, the MCP server and reverse SSH run through separate LaunchAgents, and autossh automatically restores the tunnel after drops.

As a result, the external model gets access to project memory without moving the memory itself to the cloud.

Back to contents

Where MCP ends and what comes next

Today Obsidian MCP is a working part of my system.

Through it a language model can search Obsidian, open notes, assemble project context and work with files.

That’s exactly the problem I originally wanted to solve.

But with use, the next boundary became visible.

MCP solves the problem of access well.

The model gets a set of tools and decides for itself what to search for, which notes to open and what context to assemble.

But looking further ahead, what I need is no longer just the ability to reach files.

I need a separate system that itself understands how my project memory is organised.

So the next stage became the Obsidian Knowledge Agent.

That project is currently in active development.

To simplify the difference a lot, MCP looks roughly like this:

The LLM reaches Obsidian through tools and assembles the context it needs on its own.

The Knowledge Agent should work differently.

It gets its own search and indexing layer, an understanding of project structure, of links between files and Canvas, of source rules and project boundaries.

So in front of the model there will be a separate system that first determines where to look, what relates to the question and what context really needs to be passed on.

Working with changes shifts too.

In MCP, access to a note and the ability to change it sit quite close to each other.

In the Knowledge Agent, reading, reasoning and changing state are separated.

Finding information is one circuit.

Proposing a change is another.

And actually changing a project happens only through a separate controlled mechanism with safety rules.

As a result the role of MCP itself changes.

It doesn’t disappear.

But from the centre of the architecture it turns into one of the ways of connecting to the system.

If the current architecture can be described like this:

LLM → MCP → Obsidian

the next one gradually becomes:

LLM → Knowledge Agent → project memory

Where project memory means not only Markdown files but also project structure, Canvas, linked sources, its own index and the rules for working with all of it.

Part of this architecture is already implemented, part is still being built.

So I’ll write about the Obsidian Knowledge Agent in detail later.

And this series can end here.

MCP became the first working bridge between an LLM and my memory.

The next stage is no longer about giving a model access to knowledge.

It’s about building a system that knows how to work with that knowledge.

Back to contents

Next seriesVoxBase