Why Whisper isn't the main thing here: VAD, chunks and audio preparation
Transcription is usually described like this:
audio › Whisper › text
But quality is often decided before Whisper starts.
The main question:
what exactly are we sending to the model?
A recording may contain an hour of sound but nowhere near an hour of speech.
Pauses. Waiting. Background noise. Random sounds. Long stretches where nobody says anything.
If you send it all, the model spends time on emptiness, loses context and sometimes starts finding words where there were none.
So VoxBase first builds a speech map.
audio › Silero VAD › speech islands › chunks › Whisper
VAD, Voice Activity Detection, doesn’t recognise words. It answers a simpler question: where is a person speaking, and where not?
segments = detect_speech(audio)
chunks = merge_segments(segments, target_sec=60)

for chunk in chunks:
text = whisper(chunk)- detect_speech() finds the start and end of each speech section
- merge_segments() gathers small sections into roughly one-minute blocks
- only after that is each block sent to Whisper
Why not transcribe each short segment separately?
Because on fragments of 1–2 seconds Whisper loses context and starts hallucinating.
So VoxBase gathers small lines into chunks of about 60 seconds of speech.
Not the whole file. Not separate scraps. Blocks big enough for the model to understand the context.
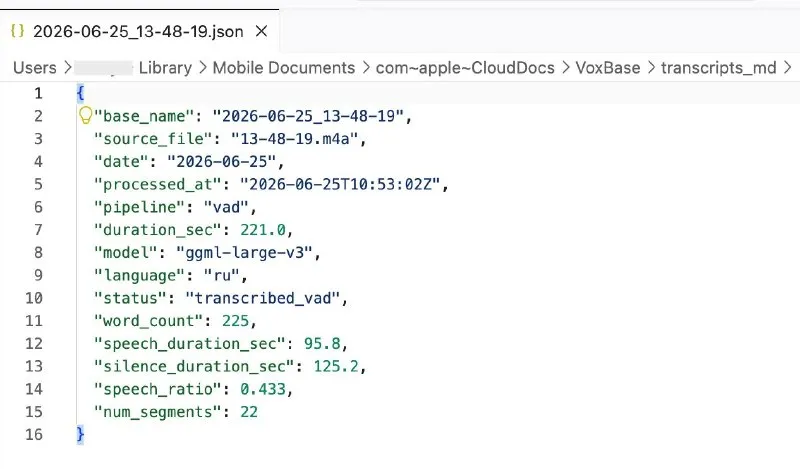
In one test a 26-minute recording contained 131 speech segments. VoxBase gathered them into just 4 proper chunks.
In another test:
62 minutes of audio › 574 speech segments › 42:50 of actual speech › 30.9% silence skipped
So almost a third of the file didn’t need transcribing at all.
Before Whisper, each chunk also goes through ffmpeg:
- converted to mono
- brought to 16 kHz
- cleaned of some of the noise
- normalised for loudness
- saved as a working WAV
And only then does the local large-v3 model start.
The main idea turned out to be simple:
good transcription doesn’t begin with choosing a model. It begins with not making the model listen to garbage.
VoxBase first separates speech from sound, restores a convenient context and only then asks Whisper to recognise the words.
raw sound › speech map › clean chunks › Whisper › transcript with original timecodes
So Whisper matters here, but it’s only the last worker on the line.